 PluginStats
fetcher-mcp weekly downloads statistics
By jaeger · npm · MCP servers
MCP server for fetching web content using Playwright browser
fetcher-mcp has 12,136 recorded weekly downloads on npm.
About fetcher-mcp
中文 | Deutsch | Español | français | 日本語 | 한국어 | Português | Русский
Fetcher MCP
MCP server for fetch web page content using Playwright headless browser.
🌟 Recommended: OllaMan - Powerful Ollama AI Model Manager.
Advantages
-
JavaScript Support: Unlike traditional web scrapers, Fetcher MCP uses Playwright to execute JavaScript, making it capable of handling dynamic web content and modern web applications.
-
Intelligent Content Extraction: Built-in Readability algorithm automatically extracts the main content from web pages, removing ads, navigation, and other non-essential elements.
-
Flexible Output Format: Supports both HTML and Markdown output formats, making it easy to integrate with various downstream applications.
-
Parallel Processing: The
fetch_urlstool enables concurrent fetching of multiple URLs, significantly improving efficiency for batch operations. -
Resource Optimization: Automatically blocks unnecessary resources (images, stylesheets, fonts, media) to reduce bandwidth usage and improve performance.
-
Robust Error Handling: Comprehensive error handling and logging ensure reliable operation even when dealing with problematic web pages.
-
Configurable Parameters: Fine-grained control over timeouts, content extraction, and output formatting to suit different use cases.
Quick Start
Run directly with npx:
npx -y fetcher-mcp
First time setup - install the required browser by running the following command in your terminal:
npx playwright install chromium
HTTP and SSE Transport
Use the --transport=http parameter to start both Streamable HTTP endpoint and SSE endpoint services simultaneously:
npx -y fetcher-mcp --log --transport=http --host=0.0.0.0 --port=3000
After startup, the server provides the following endpoints:
/mcp- Streamable HTTP endpoint (modern MCP protocol)/sse- SSE endpoint (legacy MCP protocol)
Clients can choose which method to connect based on their needs.
Debug Mode
Run with the --debug option to show the browser window for debugging:
npx -y fetcher-mcp --debug
Configuration MCP
Configure this MCP server in Claude Desktop:
On MacOS: ~/Library/Application Support/Claude/claude_desktop_config.json
On Windows: %APPDATA%/Claude/claude_desktop_config.json
{
  "mcpServers": {
    "fetcher": {
      "command": "npx",
      "args": ["-y", "fetcher-mcp"]
    }
  }
}
Docker Deployment
Running with Docker
docker run -p 3000:3000 ghcr.io/jae-jae/fetcher-mcp:latest
Deploying with Docker Compose
Create a docker-compose.yml file:
version: "3.8"

services:
  fetcher-mcp:
    image: ghcr.io/jae-jae/fetcher-mcp:latest
    container_name: fetcher-mcp
    restart: unless-stopped
    ports:
      - "3000:3000"
    environment:
      - NODE_ENV=production
    # Using host network mode on Linux hosts can improve browser access efficiency
    # network_mode: "host"
    volumes:
      # For Playwright, may need to share certain system paths
      - /tmp:/tmp
    # Health check
    healthcheck:
      test: ["CMD", "wget", "--spider", "-q", "http://localhost:3000"]
      interval: 30s
      timeout: 10s
      retries: 3
Then run:
docker-compose up -d
Features
-
fetch_url- Retrieve web page content from a specified URL- Uses Playwright headless browser to parse JavaScript
- Supports intelligent extraction of main content and conversion to Markdown
- Supports the following parameters:
url: The URL of the web page to fetch (required parameter)timeout: Page loading timeout in milliseconds, default is 30000 (30 seconds)waitUntil: Specifies when navigation is considered complete, options: 'load', 'domcontentloaded', 'networkidle', 'commit', default is 'load'extractContent: Whether to intelligently extract the main content, default is truemaxLength: Maximum length of returned content (in characters), default is no limitreturnHtml: Whether to return HTML content instead of Markdown, default is falsewaitForNavigation: Whether to wait for additional navigation after initial page load (useful for sites with anti-bot verification), default is falsenavigationTimeout: Maximum time to wait for additional navigation in milliseconds, default is 10000 (10 seconds)disableMedia: Whether to disable media resources (images, stylesheets, fonts, media), default is truedebug: Whether to enable debug mode (showing browser window), overrides the --debug command line flag if specified
-
fetch_urls- Batch retrieve web page content from multiple URLs in parallel- Uses multi-tab parallel fetching for improved performance
- Returns combined results with clear separation between webpages
- Supports the following parameters:
urls: Array of URLs to fetch (required parameter)- Other parameters are the same as
fetch_url
-
browser_install- Install Playwright Chromium browser binary automatically…
Description from the npm listing.
- mcp
- playwright
- web-scraping
- readability
- content-extraction
README badge
Show your rank in a README or on your website. The badge updates automatically.
Charts
Images: 30d · 1y · all time · 1600×900 dark


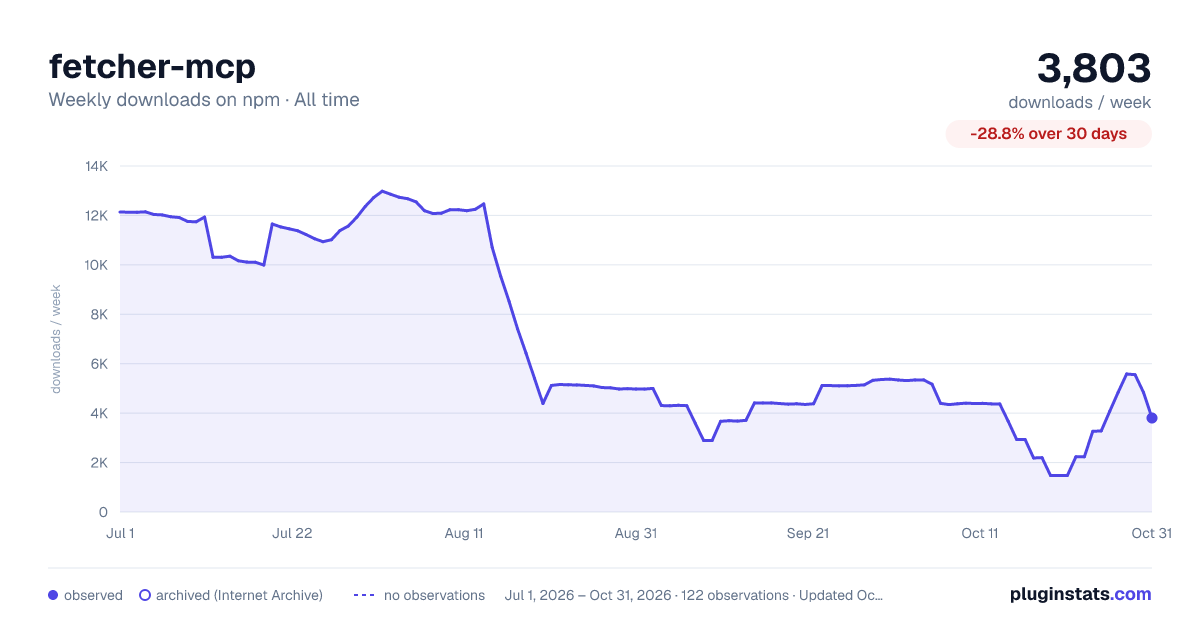

Adoption over time
7/30/90-day growth
Ranking history
Listing placement
Listing placement
Filled points are observed values; hollow points come from Internet Archive snapshots of the listing page. Dashed segments span periods with no observations — values between points are not interpolated.
Each band is one page of 20. Weekly downloads on a linear scale. Placement is projected from weekly downloads, so it can differ from the marketplace's own sort order. Hover a dot to see the listing.
Recent observations
Full history (1)Similar npm MCP servers plugins
All 20 fetcher-mcp alternativesData source
Weekly downloads (trailing 7 complete days) come from the official npm downloads API. Downloads include CI and mirrors and are not equivalent to installs or users. npm publishes no ratings.
Listing: https://www.npmjs.com/package/fetcher-mcp. First seen Oct 27, 2026; last successful collection Oct 27, 2026. See the methodology.