 PluginStats
@byokit/dictation has 477 recorded weekly downloads on npm, ranking #1508 of 2,644 tracked listings.
About @byokit/dictation
@byokit/dictation
Dictation and recording transcription using your subscription or an on-device engine. Returns text to your app with stable partials, final segments, language, timestamps and usage. Never sends the transcript anywhere on your behalf.
import { Dictation, type AudioMic } from '@byokit/dictation';
import { chatgptEngine } from '@byokit/dictation/node';
import { provider, type Accounts } from '@byokit/accounts';

// Supplied by your app: its accounts instance, selected member and microphone.
declare const accounts: Accounts;
declare const person: string;
declare const yourMicrophonePort: AudioMic;
declare function showText(text: string): void;
const engine = chatgptEngine({
  access: async signal => {
    signal?.throwIfAborted();
    const runtime = await accounts.runtime(person);
    const id = provider('chatgpt').pi;
    const auth = await runtime.getAuth(id); // refresh under the accounts store's lock
    const credential = await runtime.readCredential(id);
    return { access: auth?.auth.apiKey ?? '',
      accountId: credential?.type === 'oauth' && typeof credential.accountId === 'string' ? credential.accountId : undefined };
  },
});
const dictation = new Dictation({ engine, audio: yourMicrophonePort });
const listening = dictation.listen();
listening.on('final', ({ segment }) => showText(segment.text));
const result = await listening.finish();
// Your app decides whether to insert or send result.text.
For on-device Node transcription, import whisperEngine from ./node and pass absolute binary and modelPath paths. The kit never discovers a CLI, model, sign-in, environment key or another tool's state. transcribe(bytesOrBlob, options) accepts recordings; Uint8Array input is WAV, while Blob supplies a media type for compressed files. Language uses languages[0] (one recognition language at a time); replacements apply only to finals. Whisper expects 16 kHz WAV; your app decodes other formats first.
For browser/PWA and React Native, the main entry has no Node or native imports. Inject systemEngine(native) or a DictateEngine provided by your app's worker/native binding. The system port must enforce on-device recognition and provide a stop() that settles final callbacks before resolving. Capture belongs to the app; shared speech detection lives in @byokit/audio. The PCM port delivers mono Int16Array frames at 16 kHz. Its idempotent stop() must stop production, unblock iteration and leave every already captured frame available to the iterator before it ends. finish() drains those frames before final inference, including audio queued during an in-flight preview; cancel() discards them. HTTP providers run on a Node host child and can be exposed through an app-owned engine transport without giving the phone account credentials.
routes() lists local and ChatGPT subscription routes by default. OpenAI and OpenRouter API key (billed per use) routes have offer: false. OpenRouter can use an accounts-managed sign-in key through access, but billing remains per use. The kit applies no experimental flag to ChatGPT; refusal reports not-included. It uses its own originator.
Live system recognition emits partial/final text; Whisper rereads once a second and stabilizes partials. The RN engine makes a fresh reading of the complete recording at finish; other reread engines settle on silence. Cloud engines return finals after each utterance rather than native streaming deltas. onDeviceOnly: true rejects cloud engines before capture/credential access. finish() settles once and releases capture; cancel() stops capture and aborts inference. finish() after cancellation rejects with cancelled. listen({ maxSeconds: 300 }) bounds app-injected PCM capture to five minutes by default, including silence and previously settled turns; a finite positive setting overrides it. Invalid settings return unsupported before opening capture; exceeding the limit stops capture and returns too-large from finish(). Native system recognizers own their capture limits. Files remain limited to 25 MB, and child inference defaults to a 60-second timeout.
Timestamp support follows the engine: OpenAI word timestamps require whisper-1, Whisper CLI uses segment offsets/token offsets where available, and ChatGPT has no language/timestamp controls. Unknown cost/duration is not estimated. installModel delegates storage/download to your host and validates size plus SHA-256. Use ./testing for offline microphone and inference fakes.
See the specification and the Android consumer proof. The package is published as @byokit/dictation. The emulator flow exercises the public JavaScript entry and app-owned system port through Android SpeechRecognizer with a deterministic local RecognitionService; it does not qualify a downloaded speech model or a vendor recognizer. Native bindings remain the host app's responsibility.
On-device React Native with whisper.rn
Install whisper.rn@0.7.2 in your native host app and follow its native installation instructions. It is an optional peer: importing the kit does not import or initialize a native module. Expo requires a native development build, rather than Expo Go. Your app supplies initWhisper, a downloaded local model path or Metro require() asset, and capture. The kit downloads nothing. There is no bundled or silently selected model; DEFAULT_WHISPER_MODEL recommends base.en-q5_1 (about 60 MB), measured below; it is an identity, not a downloaded file or an accuracy guarantee. Choose a multilingual model for other languages and pass multilingual: true to default to auto, or select an explicit recognition language.…
Description from the npm listing.
- typescript
- ai
- ai-sdk
- react-native
- web
- privacy
README badge
Show your rank in a README or on your website. The badge updates automatically.
Charts
Images: 30d · 1y · all time · 1600×900 dark


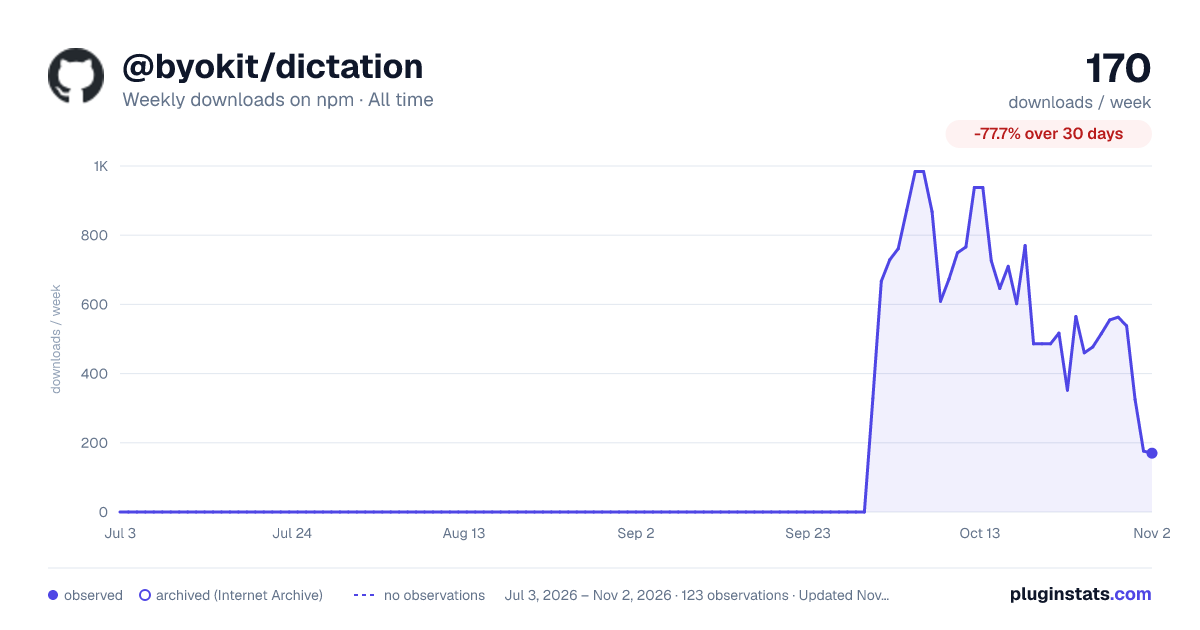

Adoption over time
7/30/90-day growth
Ranking history
Listing placement
Listing placement
Filled points are observed values; hollow points come from Internet Archive snapshots of the listing page. Dashed segments span periods with no observations — values between points are not interpolated.
Each band is one page of 20. Weekly downloads on a linear scale. Placement is projected from weekly downloads, so it can differ from the marketplace's own sort order. Hover a dot to see the listing.
Recent observations
Full history (1)Similar npm AI SDKs plugins
All 20 @byokit/dictation alternativesData source
Weekly downloads (trailing 7 complete days) come from the official npm downloads API. Downloads include CI and mirrors and are not equivalent to installs or users. npm publishes no ratings.
Listing: https://www.npmjs.com/package/@byokit/dictation. First seen Oct 28, 2026; last successful collection Oct 28, 2026. See the methodology.