 PluginStats
@tavily/ai-sdk has 7,320 recorded weekly downloads on npm, a decrease of 52.5% over the past 30 days, ranking #999 of 2,256 tracked listings.
About @tavily/ai-sdk
@tavily/ai-sdk
AI SDK tools for Tavily, compatible with Vercel's AI SDK v5 and v6.
Features
• Search: Real-time web search optimized for AI applications • Extract: Clean, structured content extraction from URLs • Crawl: Intelligent website crawling at scale • Map: Website structure discovery and mapping
Installation
Prerequisites
You need a Tavily API key to use these tools. Get one at tavily.com.
Set your API key as an environment variable:
Or pass it directly to the tool configuration.
Usage
Tavily Search
Search the web for real-time, AI-optimized information:
Configuration Options: • apiKey?: string - Tavily API key (defaults to TAVILY_API_KEY env var) • searchDepth?: "basic" | "advanced" - Search depth (default: "basic") • topic?: "general" | "news" | "finance" - Search category (default: "general") • includeImages?: boolean - Include images in results (default: false) • includeAnswer?: boolean - Include AI-generated answer (default: false) • maxResults?: number - Maximum results to return (default: 5) • includeImageDescriptions?: boolean - Include AI-generated image descriptions • includeRawContent?: false | "markdown" | "text" - Include raw content in specified format • includeDomains?: string[] - List of domains to include in search • excludeDomains?: string[] - List of domains to exclude from search • maxTokens?: number - Maximum number of tokens in response • timeRange?: "year" | "month" | "week" | "day" | "y" | "m" | "w" | "d" - Time range for results • chunksPerSource?: number - Number of content chunks per source • country?: string - Country code for localized results • startDate?: string - Start date for results (YYYY-MM-DD format) • endDate?: string - End date for results (YYYY-MM-DD format) • days?: number - Number of days back to search (for news/finance topics) • autoParameters?: boolean - Enable automatic parameter optimization • timeout?: number - Request timeout in milliseconds • includeFavicon?: boolean - Include favicon URLs in results • includeUsage?: boolean - Whether to include credit usage information in the response. • proxies?: { http?: string, https?: string } - HTTP/HTTPS proxy configuration • apiBaseURL?: string - Custom API base URL
Tavily Extract
Extract clean, structured content from URLs:
Configuration Options: • apiKey?: string - Tavily API key (defaults to TAVILY_API_KEY env var) • includeImages?: boolean - Include images in extracted content (default: false) • extractDepth?: "basic" | "advanced" - Extraction depth (default: "basic") • format?: "markdown" | "text" - Output format (default: "markdown") • timeout?: number - Request timeout in milliseconds • includeFavicon?: boolean - Include favicon URLs in results • includeUsage?: boolean - Whether to include credit usage information in the response. NOTE:The value may be 0 if the total successful URL extractions has not yet reached 5 calls. See our Credits & Pricing documentation for details. • proxies?: { http?: string, https?: string } - HTTP/HTTPS proxy configuration • apiBaseURL?: string - Custom API base URL
Input Parameters (for AI agent): • urls: string[] - Array of URLs to extract content from (required) • extractDepth?: "basic" | "advanced" - Override extraction depth per call
Tavily Crawl
Crawl websites to discover and extract content from multiple pages:
Configuration Options: • apiKey?: string - Tavily API key (defaults to TAVILY_API_KEY env var) • maxDepth?: number - Maximum crawl depth (1-5, default: 1) • maxBreadth?: number - Maximum pages per depth level (1-100, default: 20) • limit?: number - Maximum total pages to crawl (default: 50) • extractDepth?: "basic" | "advanced" - Content extraction depth • instructions?: string - Natural language crawling instructions • selectPaths?: string[] - Path patterns to include (e.g., ["/blog/"]) • selectDomains?: string[] - Domains to include • excludePaths?: string[] - Path patterns to exclude (e.g., ["/admin/"]) • excludeDomains?: string[] - Domains to exclude • allowExternal?: boolean - Allow crawling external domains (default: false) • includeImages?: boolean - Include images in extracted content • format?: "markdown" | "text" - Output format (default: "markdown") • timeout?: number - Request timeout in milliseconds • includeFavicon?: boolean - Include favicon URLs in results • includeUsage?: boolean - Whether to include credit usage information in the response. NOTE:The value may be 0 if the total use of /extract and /map have not yet reached minimum requirements. See our Credits & Pricing documentation for details. • proxies?: { http?: string, https?: string } - HTTP/HTTPS proxy configuration • apiBaseURL?: string - Custom API base URL
Input Parameters (for AI agent): • url: string - Base URL to start crawling from (required) • maxDepth?: number - Override maximum crawl depth per call • extractDepth?: "basic" | "advanced" - Override extraction depth per call • instructions?: string - Override or specify crawling instructions per call • allowExternal?: boolean - Override external domain crawling setting per call
Tavily Map
Map website structure to understand site architecture:…
Description from the npm listing.
- ai
- ai-sdk
- tools
- tavily
- search
- web-search
- crawl
- extract
README badge
Show your rank in a README or on your website. The badge updates automatically.
Charts
Images: 30d · 1y · all time · 1600×900 dark


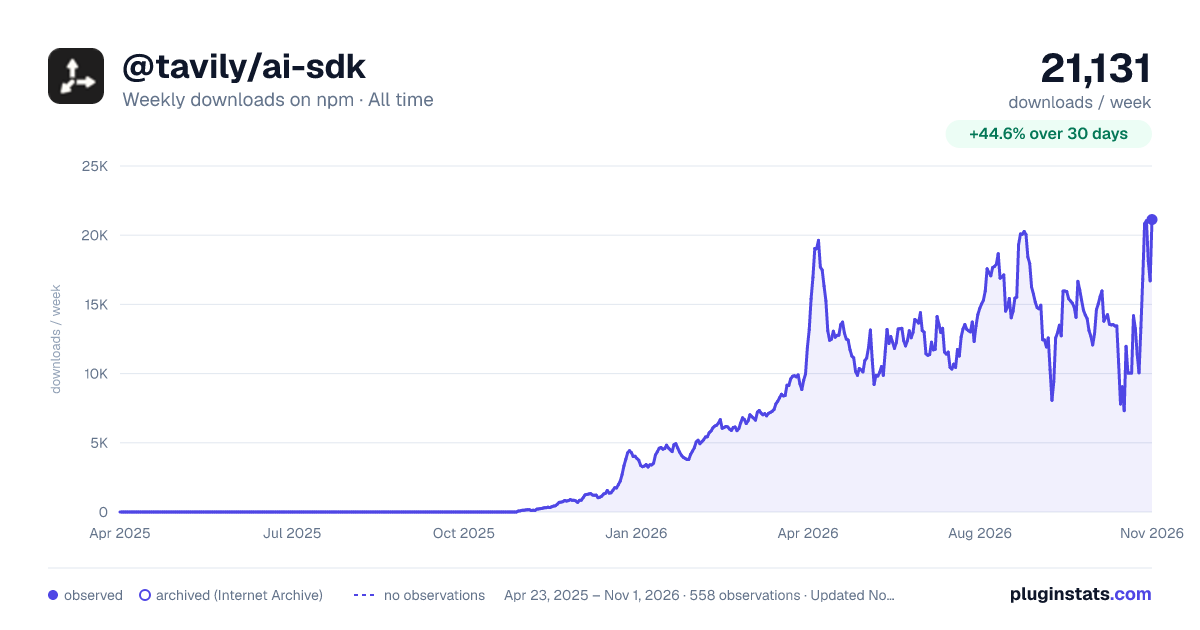

Adoption over time
7/30/90-day growth
Ranking history
Listing placement
Listing placement
Filled points are observed values; hollow points come from Internet Archive snapshots of the listing page. Dashed segments span periods with no observations — values between points are not interpolated.
Each band is one page of 20. Weekly downloads on a linear scale. Placement is projected from weekly downloads, so it can differ from the marketplace's own sort order. Hover a dot to see the listing.
Recent observations
Full history (543)Similar npm AI SDKs plugins
All 20 @tavily/ai-sdk alternativesData source
Weekly downloads (trailing 7 complete days) come from the official npm downloads API. Downloads include CI and mirrors and are not equivalent to installs or users. npm publishes no ratings.
Listing: https://www.npmjs.com/package/@tavily/ai-sdk. First seen Oct 16, 2026; last successful collection Oct 19, 2026. See the methodology.