 PluginStats
@gnldev/evals has 408 recorded weekly downloads on npm, ranking #1611 of 2,391 tracked listings.
About @gnldev/evals
@gnldev/evals
Scorers + LLM judge for @gnldev/durable runs. scoreRun reads from the journal trace → deterministic &
replayable scores (memoized if the journal is writable → same score on resume). evalDataset runs a
resumable suite (picks up where it left off if interrupted).
Install:
pnpm add @gnldev/evals— or use it from a repo clone:pnpm install && pnpm -r build.
npm i @gnldev/evals # peer: @gnldev/durable, ai
import { scoreRun, contains, llmJudge, evalDataset } from '@gnldev/evals';

// Score a single run.
const s = await scoreRun(journal, 'order-1', [contains('Charged'), llmJudge({ model, rubric: 'is it polite?' })]);

// Dataset suite (resumable).
const r = await evalDataset({
  journal,
  dataset: { id: 'd1', cases: [{ id: 'c1', input: 'x', expected: 'echo:x' }] },
  run: async (input) => `echo:${input}`,
  scorers: [contains('echo')],
});
API
- Rule-based scorers:
exactMatch,contains,regexScore,embeddingSimilarity llmJudge({ model, rubric })— general-purpose LLM judge (parses SCORE/REASON)- Ready-made LLM-judge scorers (thin factories wrapping
llmJudge, take{ model }):faithfulness,hallucination,answerRelevancy,toxicity,bias,completeness,contextPrecision,toneConsistency. For all of them, a higher SCORE = better. The ones that need context (faithfulness/hallucination/contextPrecision) readsample.context(string | string[]); the ones that need a question (answerRelevancy/completeness) readsample.input— if it's missing they don't silently return 1, they return 0 + a clear reason. scoreRun(journal, runId, scorers, { context?, input?, expected? }) → ScoreRunResult—sample.inputis the run's own journaled input (its prompt, or the last user turn of its messages) unless you passinput.contextis not derived for you — a run's tool results are not all retrieval context — so pass it, or pass a function that picks it from the run's journal entries (e.g. your retrieval tool's results).evalDataset({ journal, dataset, run, scorers }) → EvalDatasetResult(resumable). Each case'sinputis also the scorers'sample.input(a string as is;{ prompt }/{ messages }as the prompt or last user turn; anything else as JSON). A case may carrycontext; a runner that retrieved its own returns{ output, context }, which wins.- Scorer names must be unique within one call: a score is kept under its scorer's name (result, aggregate,
journal memo), so both runners — and an agent's
scorersincreateGnl, at construction — throw on a duplicate, naming both. Give one aname(llmJudge({ name: 'polite', ... }),faithfulness({ model, name })) or rename any scorer with a spread:{ ...contains('x'), name: 'has-x' }.
How it works
Since scores are written to the journal, the eval suite is idempotent; long suites continue after a crash,
and the same input produces the same score. A memo is replayed only for what it was computed on: a score
for the same sample (output, question, expected, context) and the same scorer, a dataset case for the same
case and the same scorers. A scorer is known by its name and its fingerprint: the built-in factories set
it from their options (an llmJudge rubric and model, contains' substring), and a scorer without one is
known by the source of its score. Set fingerprint yourself when a custom scorer's behaviour comes from
values it closes over ({ name: 'tone', fingerprint: optionsFingerprint('tone', { rubric }), score }).
Anything else — another expected, an edited rubric, a scorer added to the suite, a score memoized by
0.9.0 before the runners passed the question — is computed again and replaces the record. The sample for
a run has one builder in @gnldev/durable (runScoreSample, with scoreRunMemoized for the memo), and
scoreRun and an agent's scorers both call it: a run the agent scored at completion is replayed when
it is scored again from Studio, not judged twice.
License
Apache-2.0 — see LICENSE.
Description from the npm listing.
- ai
- agent
- llm
- typescript
- ai-sdk
- durable
- exactly-once
- scorers
- evaluation
- testing
README badge
Show your rank in a README or on your website. The badge updates automatically.
Charts
Images: 30d · 1y · all time · 1600×900 dark


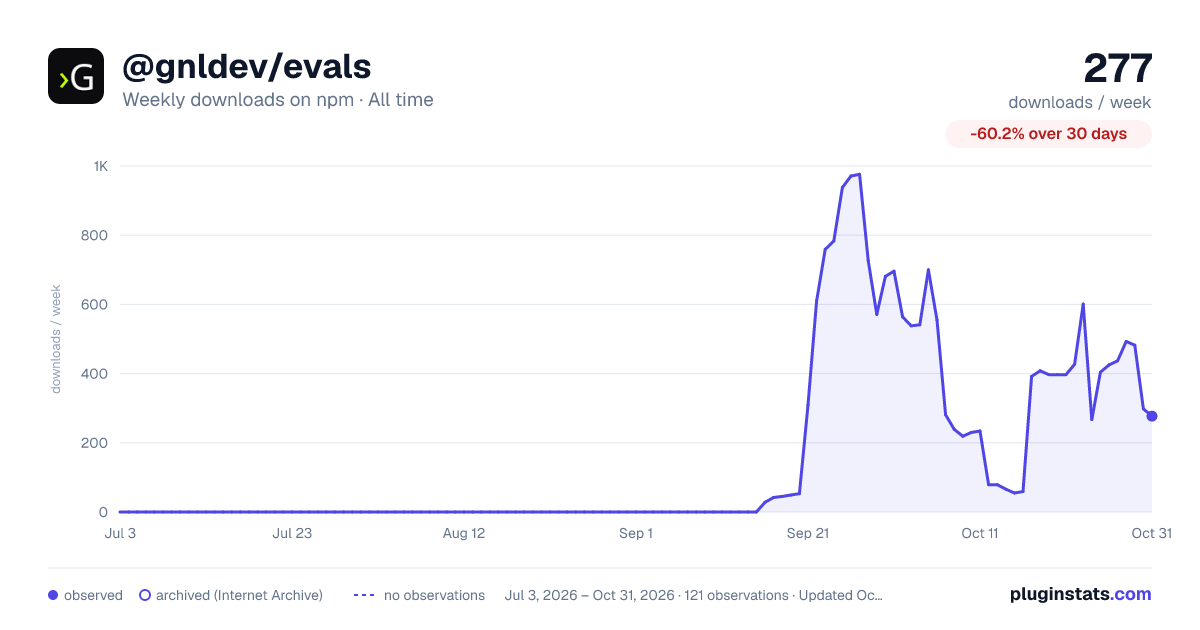

Adoption over time
7/30/90-day growth
Ranking history
Listing placement
Listing placement
Filled points are observed values; hollow points come from Internet Archive snapshots of the listing page. Dashed segments span periods with no observations — values between points are not interpolated.
Each band is one page of 20. Weekly downloads on a linear scale. Placement is projected from weekly downloads, so it can differ from the marketplace's own sort order. Hover a dot to see the listing.
Recent observations
Full history (1)Similar npm AI SDKs plugins
All 20 @gnldev/evals alternativesData source
Weekly downloads (trailing 7 complete days) come from the official npm downloads API. Downloads include CI and mirrors and are not equivalent to installs or users. npm publishes no ratings.
Listing: https://www.npmjs.com/package/@gnldev/evals. First seen Oct 21, 2026; last successful collection Oct 21, 2026. See the methodology.